

Back
Technical articles
Agent demos are easy. The harness is the hard part
Strands harness-sdk, Harness MCP Server, and HydraFusion show why agent engineering needs control over context, permissions, state, validation, and recovery.
阅读中文原文 · Translated from the original article; source publication date retained
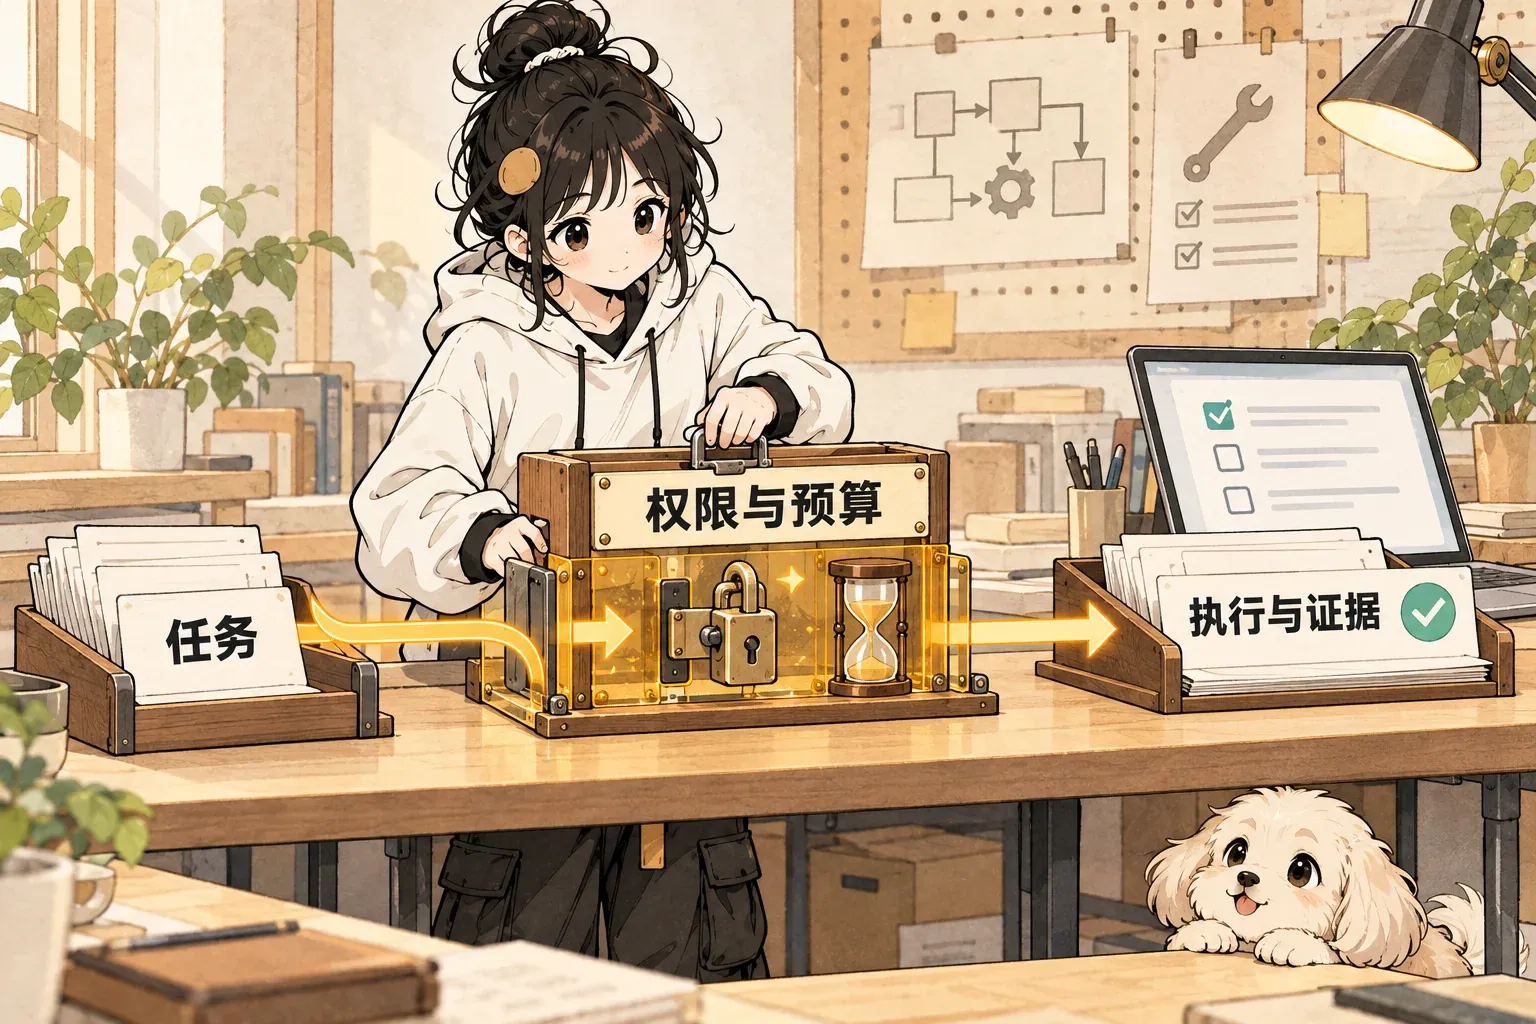
The original Chinese-language cover labels read “Task,” “Permissions and budget,” and “Execution and evidence.”
The easiest part of building an agent to show off is the demo.
Choose a model, write a prompt, register a few tools, and connect a workflow. You can have something running quickly.
But that is not the hardest part.
While looking through the official Strands Agents repository recently, I noticed a detail: the repository is called harness-sdk.
Its README puts the goal plainly: Build an agent harness. Control it end-to-end.
That is an accurate description. Once an agent becomes a product, the engineering question shifts from whether it can call a model to whether it can run reliably.
The framework assembles; the harness controls#
An agent framework usually handles these questions:
- How to call a model.
- How to register tools.
- How to pass messages.
- How to combine workflows. An agent harness handles another layer:
- When to compact context.
- How long a task may run.
- How to limit tokens and cost.
- Whether tool calls can be intercepted.
- Which operations require approval.
- Whether state can be recovered after failure.
- Whether every step has a trace.
- How to isolate permissions and state across agents.
- How to pass outputs into evaluation. The current Strands README explicitly lists context management, execution limits, observability, hooks, guardrails, MCP, streaming, multi-agent, and structured output. These capabilities share a purpose: keeping agents under control in real environments, rather than making a demo more impressive.
What a controlled agent run should leave behind
Establish the actions and targets the user actually authorized
Why the emphasis on harnesses now#
Model capabilities keep improving, and the number of model providers keeps growing. It is hard for builders to base a product advantage on knowing how to call a particular model. The control layer around the model is where engineering work can accumulate. Take a coding agent: Being able to call a shell does not mean it should have unrestricted shell permissions. Being able to execute 50 consecutive steps does not mean every task should be allowed 50 steps. Being able to read the entire repository does not mean all that context should stay in the window forever. Being able to modify files automatically does not remove the need for rollback and auditing when it fails. A prompt cannot solve these problems. They require explicit runtime mechanisms.
Harness MCP Server 2.0 makes the same point#
Another project worth looking at is Harness’s official MCP Server 2.0. It no longer exposes every API endpoint as a separate tool. The README describes 11 consolidated tools covering 243 resource types. A registry dispatcher routes requests behind them. This design addresses how a model selects among too many tools, rather than merely whether MCP can be connected. The set of tools exposed to the model is itself becoming an architecture problem. The more MCP servers you connect, the less viable it is to put every tool into the context at once.
HydraFusion takes the question further into the runtime#
Project HydraFusion, released by GitHub on September 4, takes this another step. Instead of selecting one fixed model, it chooses Single, Cascade, or Critique at runtime. Some tasks go directly to one model. Others start with a cheaper model, then use a quality threshold to decide whether to escalate. Others have one model write, a second perform a read-only review, and the original model make revisions. Model selection is becoming part of runtime orchestration too.
What builders should add now#
If you are building an agent product, I recommend drawing out these seven areas separately:
- Permissions: what each agent and tool can do.
- State: where the task is in its execution, and whether it can recover.
- Budget: limits on tokens, time, and call count.
- Context: what to retain, compact, or discard.
- Logs: whether each call, result, and error can be traced.
- Evaluation: how to verify the result automatically.
- Recovery: how to retry, fall back, and roll back after failure. These seven areas are closer to the engineering foundation of an agent product than the choice of model. Frameworks still matter, but they are more of an entry point for development. The harness determines whether an agent can operate over the long term.

End of article · Back to writing
Comments
Comments are public and managed through GitHub Discussions.
Preparing the comment section…
Sign in with GitHub once the comment box is ready, or open the repository discussions directly. Open GitHub Discussions ↗Comments are published to the public discussions of the lora-sys/loraSys repository.