

Back
Technical articles
Coding agent security is now a supply-chain problem
Coding agents read and execute skills, MCP tools, dependencies, and repository instructions. These need software supply-chain controls.
阅读中文原文 · Translated from the original article; source publication date retained
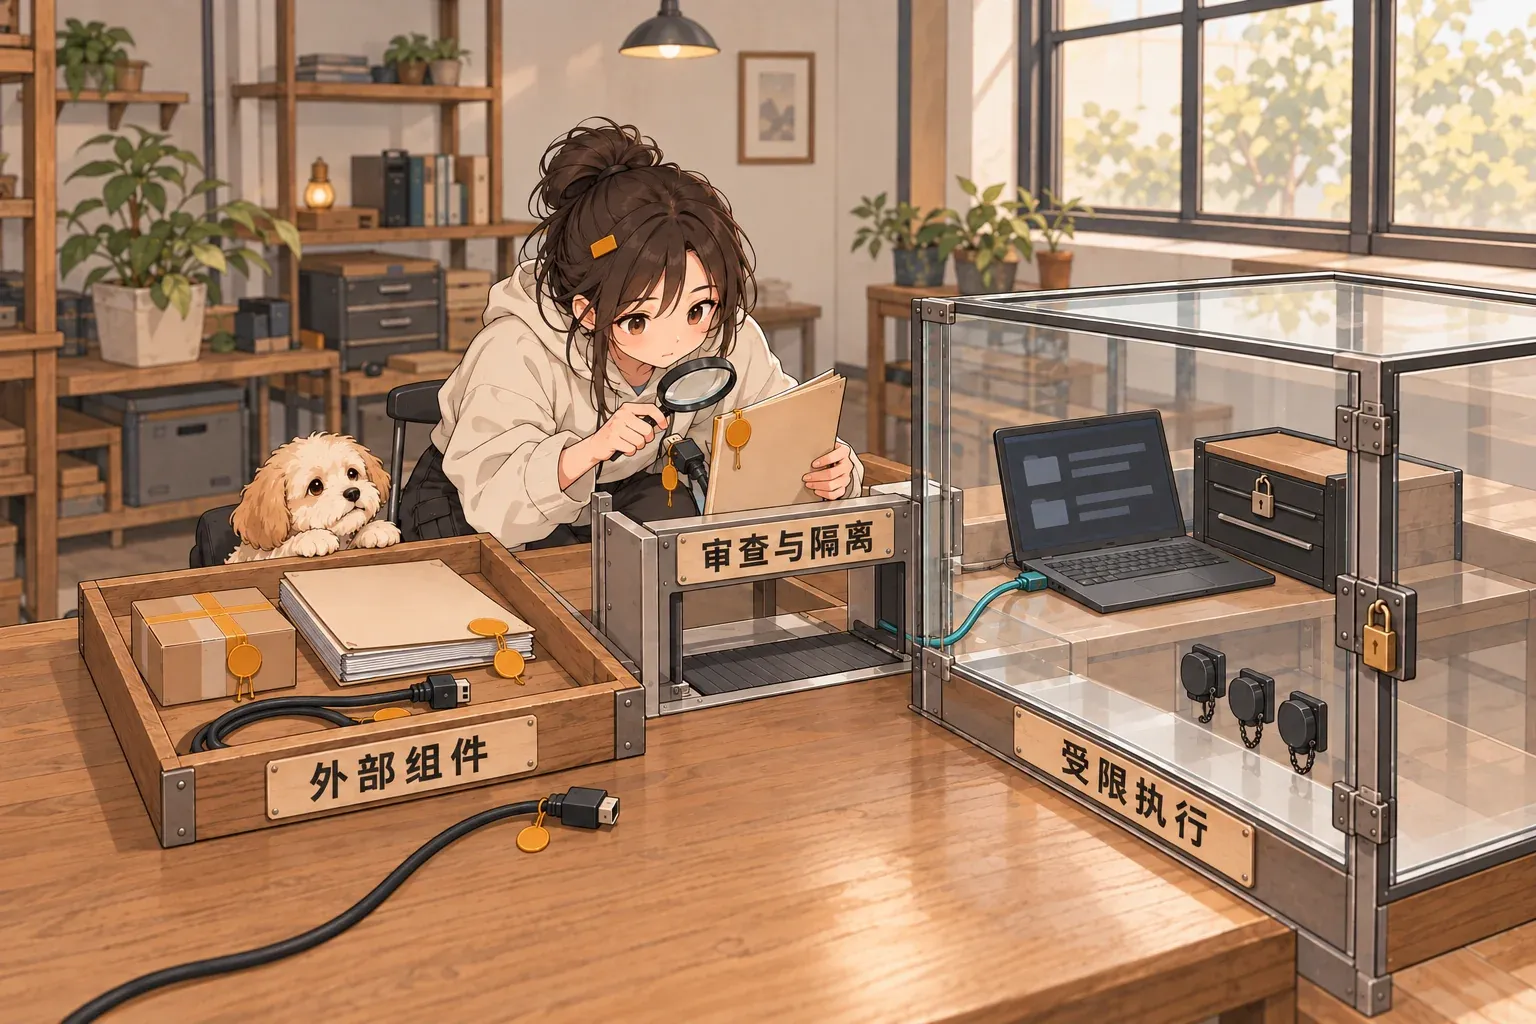
The original cover retains Chinese labels. They read “External components,” “Review and isolation,” and “Restricted execution.” The illustration shows outside components being inspected before they reach an isolated execution environment with limited access.
Coding agent security is now a supply-chain problem#
On September 8, Google Threat Intelligence Group published a new AI Threat Tracker. For builders, the report’s most important point is that attackers have begun using agents as execution systems, rather than which new attacks a model can perform. GTIG recorded an operation in the second quarter of 2026. Attackers compromised cloud resources, then completed attack planning, infrastructure setup, and large-scale credential collection. The entire process took less than 6 hours. The report also mentions a problem closer to developers. In open-source software supply-chain attacks, UNC6780 exploits the paths through which AI coding assistants and LLM security scanners encounter dependencies, repository content, and build environments. Agent security therefore has to look beyond prompts.
What will an agent trust?#
Traditional software supply-chain checks focus on code, packages, images, and build scripts. AI coding agents add another set of inputs. They read AGENTS.md ↗, CLAUDE.md ↗, skill files, MCP configurations, repository documentation, dependency manifests, and tool results. Many agents can also execute shell commands, change files, call cloud services, or operate external systems directly. These inputs share one property. They can change what the agent does next. A malicious dependency that makes a program execute the wrong code is a supply-chain risk. A malicious skill or repository instruction that makes an agent call the wrong tool, read a forbidden file, or send credentials outside is also a supply-chain risk. Only the execution path differs.
The attacks Google observed already reach the AI development chain#
GTIG’s report explicitly says attackers are targeting developers, AI coding assistants, and LLM security scanners. These attacks do not require breaking the model itself. Attackers can poison open-source dependencies, project files, or toolchains that an agent reads. If the agent treats that content as trusted input and has substantial permissions, it can amplify a traditional supply-chain problem. In earlier developer-security research, Google also divided AI coding agents’ attack surfaces into four groups: files that execute, files that instruct the agent, configurations that connect tools, and components that extend capabilities. This classification is practical because it maps directly to project files builders encounter every day.
Why skills and MCP need security review#
On September 3, Tenable announced CyberAgents Exchange AI Inspector. Its inspection scope extends beyond agents themselves. The official list includes agents, skills, MCP servers, and multi-agent playbooks. The approach is similar to a software package scanner. Installing a community skill gives an agent a set of long-term instructions. Connecting an MCP server adds callable capabilities and external data sources. Introducing a playbook adds an execution path. Each requires a known source, version, permission set, and behavioral scope. Being installable says nothing about safety.
Permission boundaries will matter more#
On the same day, Zayo launched Agentic Networking for network operations and provided a production MCP server. Its announcement explicitly says approved agents can read network context and execute authorized network changes. Once MCP can control networks, cloud resources, databases, or production systems, the security questions become concrete. Can a tool be called? Whose identity does it use? Which resources can it operate on? How does a failed call roll back? Is every call audited? The execution layer should control all of these. A prompt can tell an agent to avoid dangerous actions. A real permission boundary makes those actions impossible without authorization.
What builders can do now#
First, pin sources and versions. Do not let production agents automatically fetch the latest version of unknown skills, MCP servers, or dependencies. Record source repositories, versions, and hashes. Use an explicit upgrade process. Second, reduce tool permissions. Give each tool only the permissions its task needs. Separate reads from writes. Require separate approval for outbound sharing, deletion, payments, deployment, and network changes. Third, isolate the execution environment. Put agents that can run shell commands or code in a sandbox. Limit their view of the filesystem, network, and secrets. Do not give a development agent access to the whole machine by default. Fourth, record the chain of trust. Logs should include more than model output. Record which skills the agent loaded, which MCP servers it connected to, which external instructions it read, which tools it called, and which identity it used. Fifth, include external components in evals. After upgrading a skill, MCP server, or dependency, rerun key tasks and security tests. Check for permission violations, outbound sharing, unusual tool calls, and changes in results.
One final judgment#
Agent risk includes more than incorrect model answers. Agents execute actions, so the components they trust need auditing too. For future agent security work, I would manage skills, MCP, dependencies, and repository instructions together as an “executable chain of trust.” That boundary reflects real products more closely than discussing prompt injection alone.#

End of article · Back to writing
Comments
Comments are public and managed through GitHub Discussions.
Preparing the comment section…
Sign in with GitHub once the comment box is ready, or open the repository discussions directly. Open GitHub Discussions ↗Comments are published to the public discussions of the lora-sys/loraSys repository.