

Back
Projects & practice
Splash: a local LLM inference stack built for each model
Splash combines model packages, kernels, memory planning, and compatible local APIs into a model-specific inference stack for coding agents.
阅读中文原文 · Translated from the original article; source publication date retained
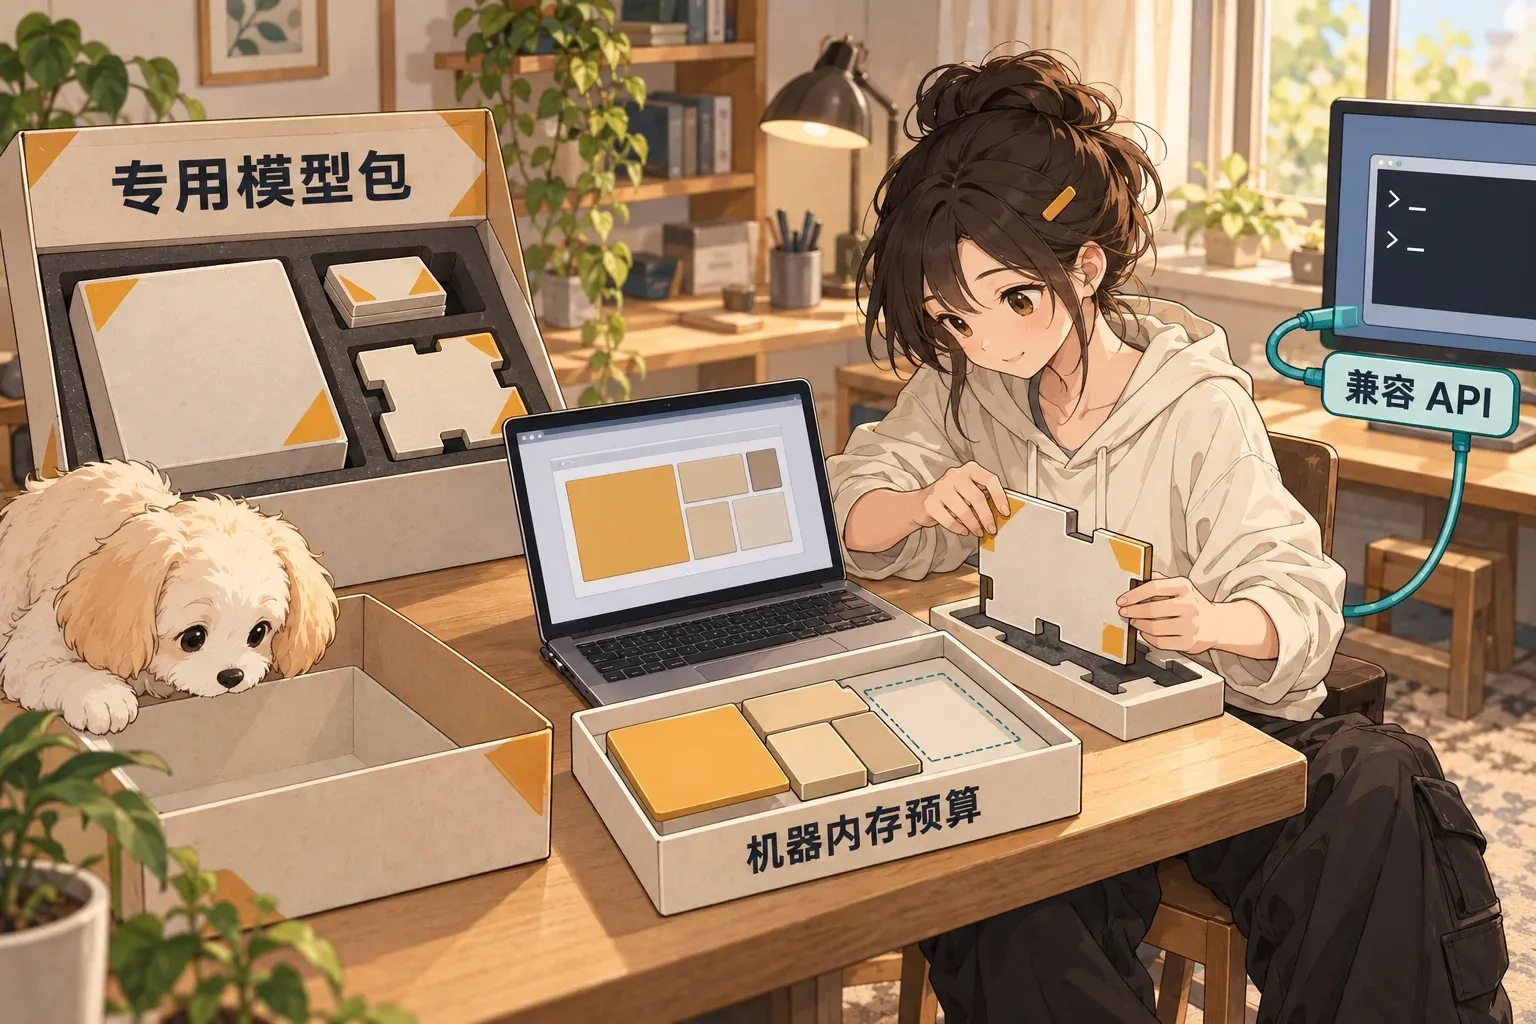
The original cover retains its Chinese labels. They mean “dedicated model package,” “machine memory budget,” and “compatible API.” The illustration shows a model-specific package assembled within the machine’s memory budget and connected to an agent through a compatible interface.
Fact check#
- Project name: Splash.
- Organization: IncoAI, with the GitHub organization
incoai. - Official repository: incoai/splash ↗.
- Official article: Splash launch post ↗.
- Core function: run a small set of specially adapted models locally on Apple silicon, exposing interfaces compatible with OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages.
- Coding-agent integration: the README provides
splash claude,splash codex,splash opencode, andsplash hermeslaunch commands. - Current model packages: the README lists
Qwen3.8-27B-SplashandQwen3.6-35B-A3B-Splash. - Key design: each model package includes its own speculative-decoding draft, Metal kernels compiled for the model’s dimensions, and a memory plan calculated for the current machine.
- Hardware requirements: Apple M3 or newer, macOS 26.4 or newer, and at least 36 GB of unified memory. The official recommendation is 48 GB or more.
- Demo: after starting the service, open the local web UI at
127.0.0.1:8000, or launch an installed coding agent directly from another terminal. - LICENSE: Apache 2.0.
- Current status: the GitHub repository is public and not archived. Splash 1.0 was released on 2026-09-18. At the time of this retrieval on 2026-09-18, new
Splash 1.0commits were still appearing that day.
Evidence cards#
- The official README ↗ describes installation requirements, supported model packages, compatible APIs, coding-agent launch commands, and the three model-specific optimizations.
- The Splash 1.0 release ↗ provides official installers, system requirements, and the 1.0 capability list.
- The Apache 2.0 LICENSE ↗ verifies the code license.
- The Splash 1.0 commit ↗ verifies the latest commit at the time of retrieval.
The 30-second version#
Splash is a local LLM inference engine that runs only on Apple silicon. Supporting more models is not its first priority. Each Splash model package includes a dedicated draft model, Metal kernels, and a memory plan. At runtime, OpenAI- and Anthropic-compatible interfaces connect the local model to tools such as Claude Code, Codex, and OpenCode. Its trade-off is clear. Narrower model support allows deeper inference optimization for specific models and Mac hardware.
Why it is interesting#
Most local inference tools build a general-purpose runtime first, then adapt it to as many models as possible. Splash takes the opposite approach. It treats each model as a complete runtime package. The draft model, weight layout, Metal kernels, and memory budget can be designed together with the model. This sacrifices model coverage, but lets engineers focus performance work on specific tensor shapes, caches, and scheduling problems. For coding agents, the design has another practical benefit. Higher-level tools keep using familiar OpenAI or Anthropic APIs. Whether inference runs in the cloud does not require a change to the agent’s call structure.
3 designs worth borrowing#
1. Include the execution strategy in the model package#
A Splash model package contains more than weights. It also includes the corresponding draft model and requires the runtime to use specialized Metal kernels matched to the model’s dimensions. The model and inference strategy ship together.
2. Calculate the machine budget at startup#
At startup, Splash calculates the current machine’s available Metal memory, subtracts the weights, draft, and request state, then decides the context, KV capacity, and batch limits. Configuration comes from the actual machine rather than one fixed set of defaults.
3. Separate the inference backend from the agent interface#
Splash exposes OpenAI- and Anthropic-compatible interfaces. Clients such as Claude Code, Codex, and OpenCode do not need to understand the underlying Metal kernels. The inference backend can be replaced independently without changing the higher-level agent workflow.
How this connects to my work#
You now regularly use Codex, Claude Code, and other coding agents together. The useful reference in Splash is how it turns local inference into a compatible backend, rather than the claim that local models are cheaper. If you later add local models to your own agent harness, you can preserve the existing OpenAI or Anthropic interface layer and put model execution, caching, and hardware optimization in an independent runtime. Higher-level agents then do not need to change along with the inference engine. The current hardware threshold is also clear. Macs with less than 36 GB of unified memory do not meet the official requirements, so this is not a lightweight local-deployment option.

End of article · Back to writing
Comments
Comments are public and managed through GitHub Discussions.
Preparing the comment section…
Sign in with GitHub once the comment box is ready, or open the repository discussions directly. Open GitHub Discussions ↗Comments are published to the public discussions of the lora-sys/loraSys repository.